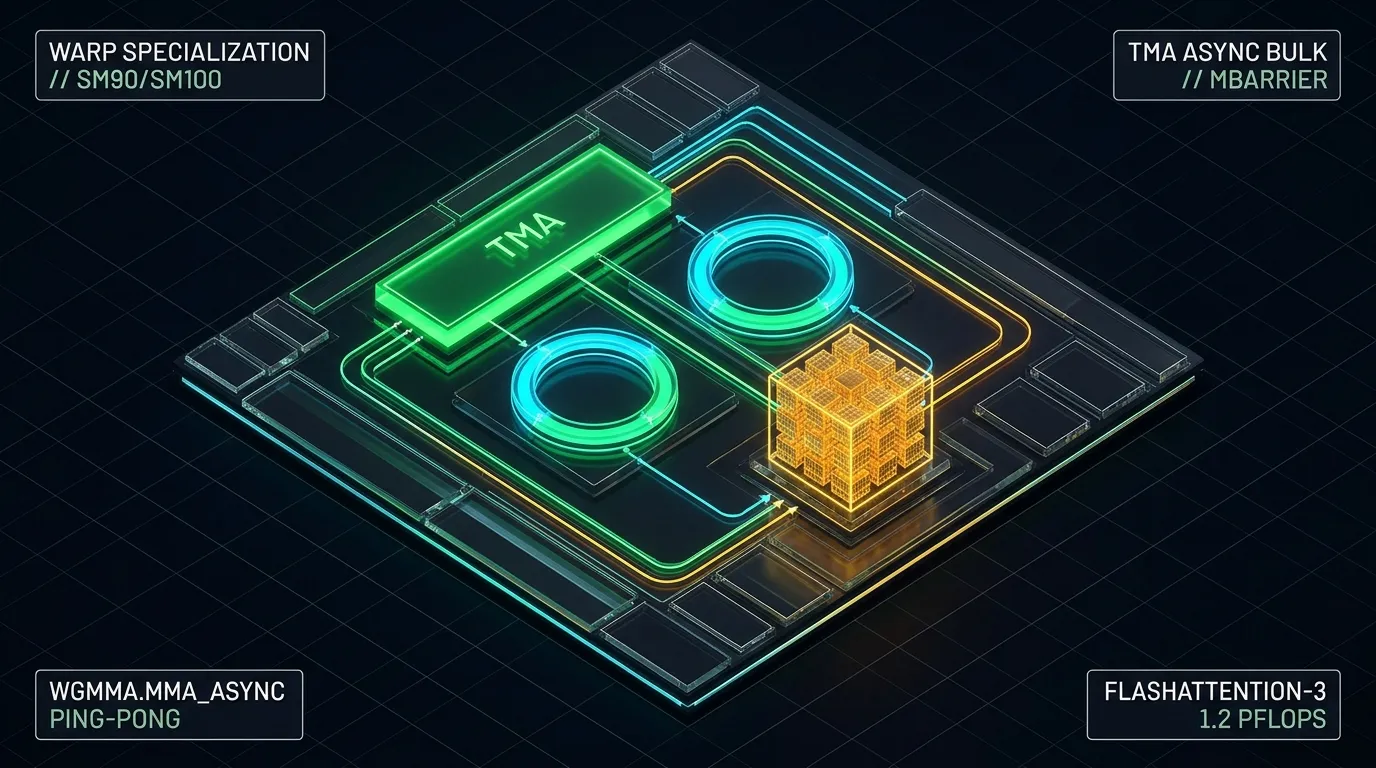
Inside FlashAttention-3 & Warp-Specialized CUDA Kernels: Asynchronous WGMMA, Tensor Memory Accelerator (TMA), and FP8 Ping-Pong Scheduling
How modern Hopper (SM90) and Blackwell (SM100) attention kernels shatter the 35% Tensor Core utilization wall by splitting threadblocks into Producer/Consumer Warpgroups with hardware TMA bulk transfers, mbarrier phase synchronization, and register-level Ping-Pong scheduling.