





#vllm
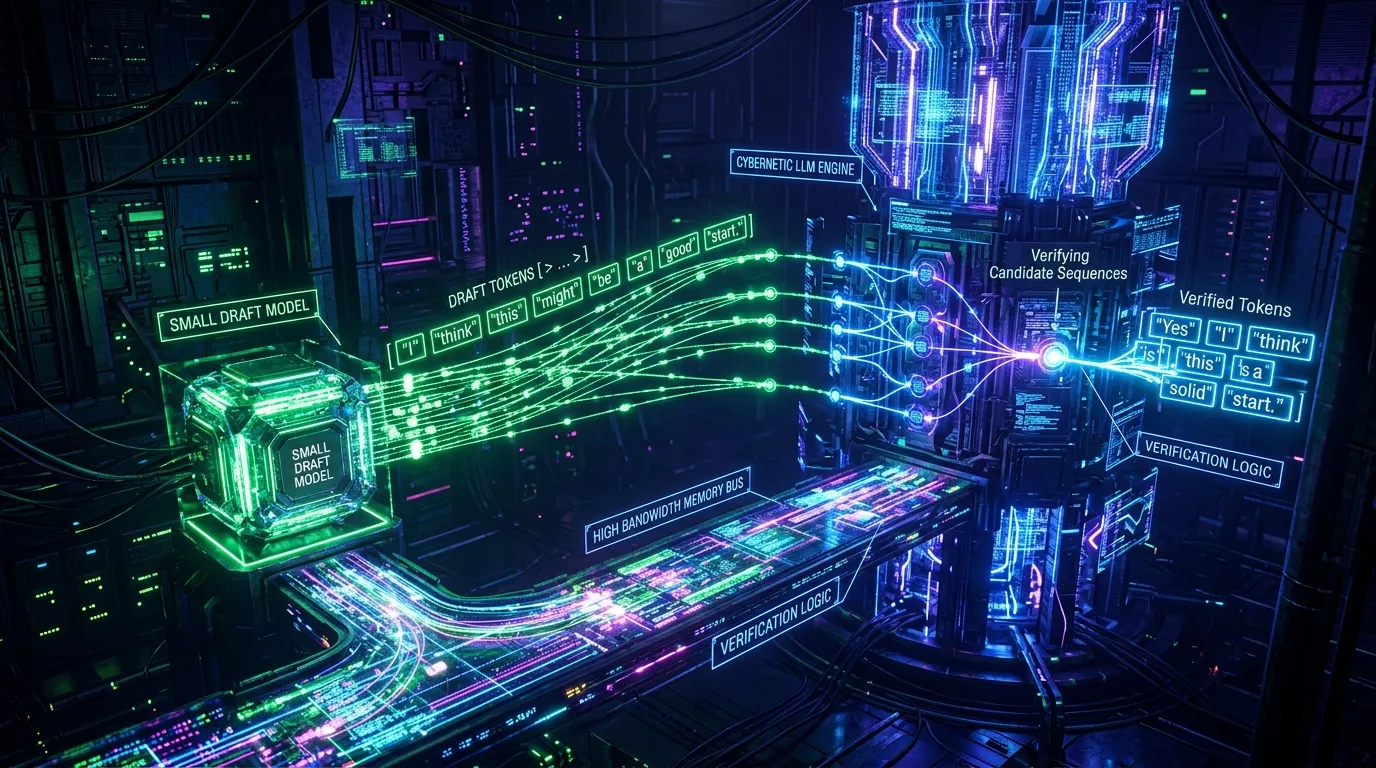
Speculative Decoding in Production: Accelerating LLM Inference Without Accuracy Loss
How speculative decoding leverages small draft models and vectorized tree verification to double generation speed on vLLM and TensorRT-LLM without sacrificing a single bit of model precision.
by Joshua Edward McLaughlin Cox
Read →