





#python
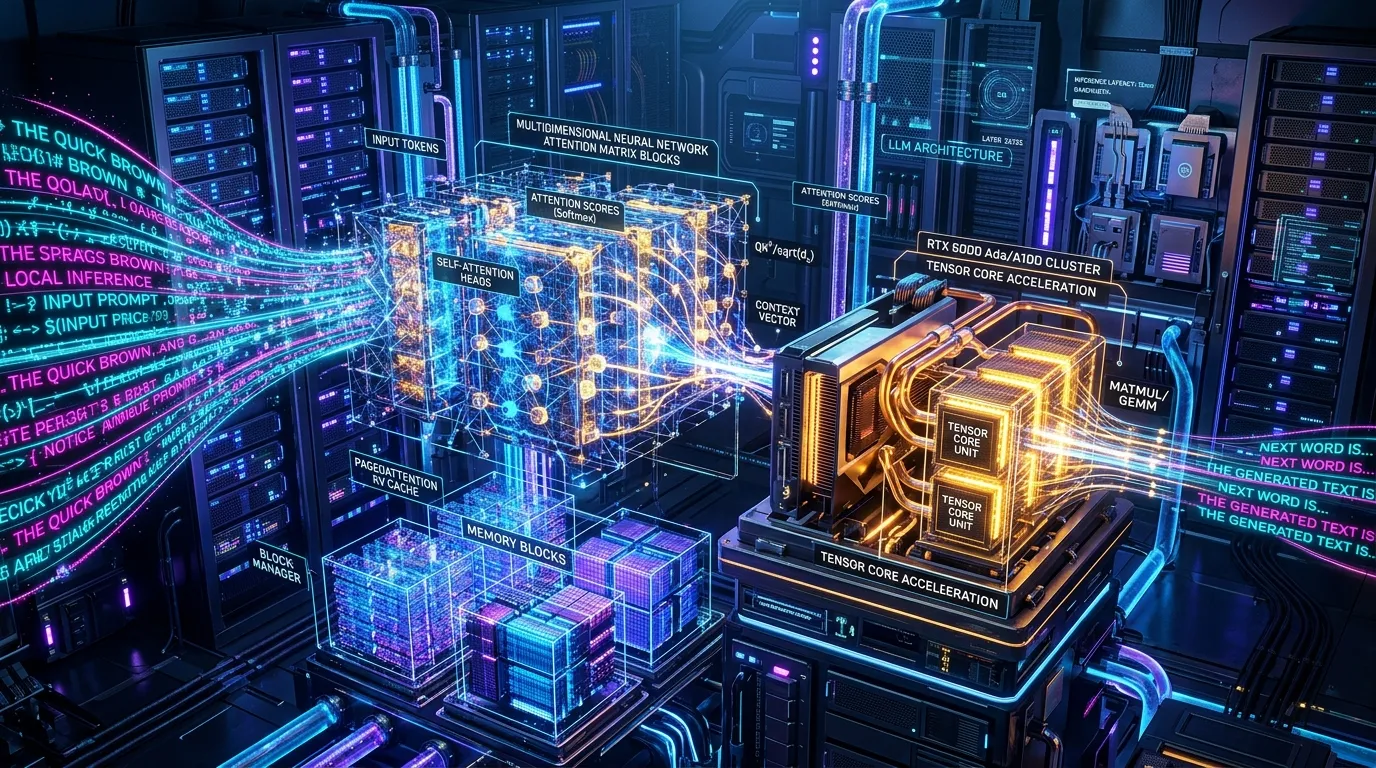
High-Throughput Local LLM Inference: vLLM, PagedAttention, and Ollama
Architecture and optimization techniques for deploying open-weight models locally with continuous batching, AWQ quantization, and GPU memory tuning.
by Joshua Edward McLaughlin Cox
Read →