




#ai-ml
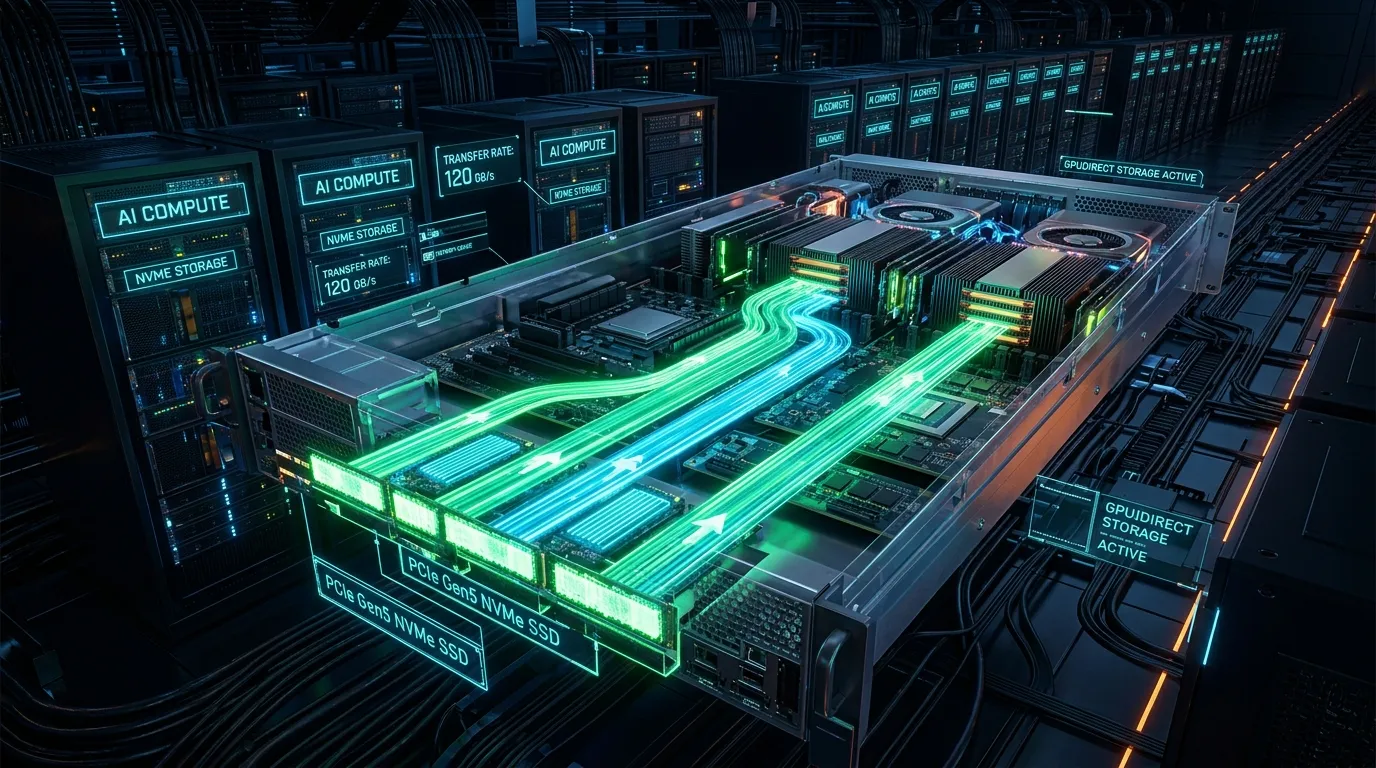
Bypassing the CPU Bottleneck: GPUDirect Storage (GDS) with NVMe-oF in AI Clusters
A deep dive into NVIDIA GPUDirect Storage (GDS) and NVMe over Fabrics: streaming massive multi-terabyte dataset shards directly into GPU HBM without CPU bounce buffers.
by Joshua Edward McLaughlin Cox
Read →