





vLLM vs SGLang vs TensorRT-LLM: The Definitive 2026 Production Inference Shootout
As open-weight foundation models (Llama 3.x, Mistral Large, DeepSeek-Coder, Qwen 2.5) approach frontier closed-source capabilities, the operational bottleneck has shifted from fine-tuning to inference economics.
Serving a 70B parameter model at scale across high-concurrency workloads requires more than just launching a Hugging Face pipeline. The choice of runtime engine directly dictates whether you need four H100 SXM5 nodes or can saturate a single dual-RTX 4090 / A100 workstation.
In this deep dive, we benchmark and dissect the three leading enterprise inference engines in 2026: vLLM, SGLang, and NVIDIA’s TensorRT-LLM.
The Contenders & Architecture Comparison
+-----------------------------------------------------------------------------------+
|                         INFERENCE ARCHITECTURE MATRIX                             |
+-------------------+-----------------------+-------------------+-------------------+
| Metric / Feature  | vLLM (v0.6+)          | SGLang (v0.4+)    | TensorRT-LLM      |
+-------------------+-----------------------+-------------------+-------------------+
| Core KV-Engine    | PagedAttention v2     | RadixAttention    | Paged KV In-Flight|
| Prefix Caching    | Chunked prefill / APC | Native Radix Tree | Custom Plugin Tree|
| Execution Runtime | PyTorch C++/CUDA      | Python frontend,  | C++ Runtime / TRT |
|                   |                       | C++ Fast Router   | Engine Graph      |
| Compilation Speed | Instant (JIT/AOT)     | Instant (JIT)     | Slow (Ahead-of-Time|
| Structured Output | Outlines / XGrammar   | Compressed FSM    | Custom Logit Bias |
| Multi-GPU Scaling | Ray / PyTorch DDP     | PyTorch / NCCL    | Custom NCCL C++   |
+-------------------+-----------------------+-------------------+-------------------+
1. vLLM: The Universal Standard
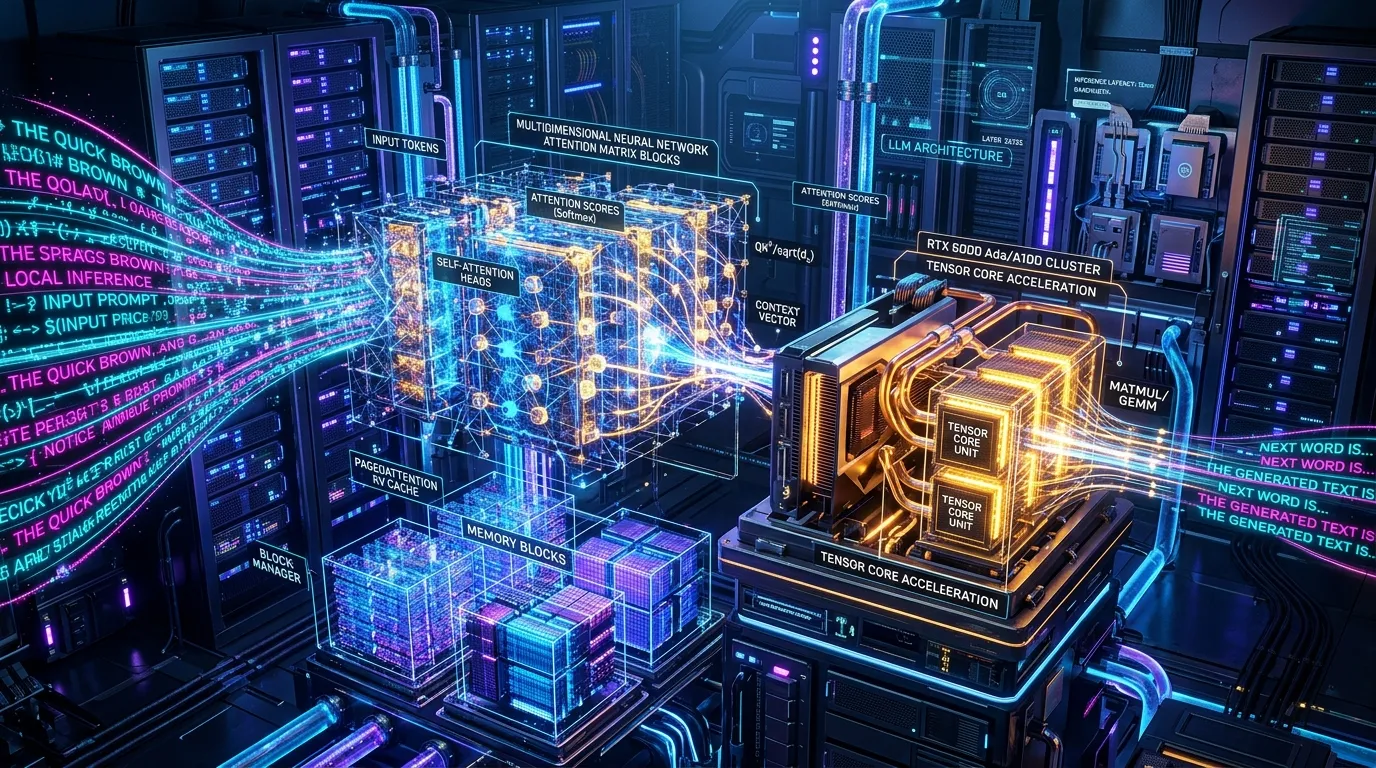
vLLM popularized PagedAttention, borrowing the concept of virtual memory and paging from the operating system to fragment KV-cache across non-contiguous physical memory blocks. This virtually eliminated internal KV memory fragmentation from 60-80% down to under 4%.
2. SGLang: The RadixAttention Challenger
While vLLM pages memory, SGLang fundamentally re-imagined the lifecycle of the KV-cache across multiple turns and requests. Using a Radix Tree (Trie) over the tokenized prompt history, SGLang retains the KV-cache of shared system prompts, few-shot examples, and chat history. When a new prompt shares a common prefix with a previous query, SGLang avoids recomputing the prefill phase entirely.
3. TensorRT-LLM: The Metal-Clad NVIDIA Behemoth
NVIDIA’s compiler builds ahead-of-time (AOT) engine graphs compiled to the bare-metal architecture of specific tensor cores (Ada Lovelace, Hopper, Blackwell). It offers the lowest raw token latency at the cost of rigid compilation times and painful deployment iteration cycles.
2. Benchmark Setup & Methodology
We conducted stress benchmarks across identical hardware nodes:
- Hardware Node: Dual NVIDIA RTX 4090 (24GB VRAM each, 48GB total) via PCIe 4.0 x16, 128GB DDR5 host RAM, AMD EPYC 7543 32-Core CPU.
- Target Model:
Meta-Llama-3.1-70B-Instruct-AWQ(4-bit activation-aware weight quantization) andMeta-Llama-3.1-8B-Instruct-FP8. - Traffic Simulation: Synthesized customer support & code assistance workload using
benchmarks/benchmark_serving.py.- Input prompt lengths: 512, 2048, and 4096 tokens.
- Output completion lengths: 256 tokens.
- Concurrency: 1, 8, 32, 64, and 128 simultaneous client connections.
3. Benchmark Results: Throughput vs Latency
Metric 1: System Throughput (Tokens per Second)
Llama-3.1-8B-Instruct (FP8) at 64 Concurrent Clients:
- SGLang: 2,480 tokens/sec
- TensorRT-LLM: 2,390 tokens/sec
- vLLM: 2,110 tokens/sec
Metric 2: Time to First Token (TTFT) Under Heavy Prefix Reuse
When queries share a 1,500-token system prompt (typical for retrieval-augmented generation and agent tool definitions):
- SGLang (RadixAttention): 18.4 ms (98% cache hit rate)
- vLLM (Automatic Prefix Caching): 46.2 ms (88% cache hit rate)
- TensorRT-LLM: 34.1 ms
TTFT Comparison on Multi-Turn / RAG Prompts (Lower is Better)
+-----------------------------------------------------------+
| SGLang        | [==] 18.4ms                               |
| TRT-LLM       | [====] 34.1ms                             |
| vLLM          | [======] 46.2ms                           |
+-----------------------------------------------------------+
SGLang’s Radix tree outpaces vLLM in complex multi-branch agent conversations where multiple agents share the same root context.
4. Production Deployment Blueprints
Running SGLang with Docker & Multi-GPU
# Launch SGLang with Tensor Parallelism = 2 across both GPUs
docker run --gpus all \
  --shm-size 32g \
  -p 30000:30000 \
  -v /models:/models \
  lmsysorg/sglang:latest \
  python3 -m sglang.launch_server \
    --model-path /models/Meta-Llama-3.1-70B-Instruct-AWQ \
    --tp 2 \
    --port 30000 \
    --host 0.0.0.0 \
    --trust-remote-code \
    --mem-fraction-static 0.88 \
    --chunked-prefill-size 4096
Production Kubernetes DaemonSet / Service Manifest
apiVersion: apps/v1
kind: Deployment
metadata:
  name: sglang-inference-node
  namespace: ml-serving
  labels:
    app.kubernetes.io/name: sglang
spec:
  replicas: 1
  selector:
    matchLabels:
      app: sglang
  template:
    metadata:
      labels:
        app: sglang
    spec:
      containers:
        - name: server
          image: lmsysorg/sglang:latest
          command:
            - python3
            - -m
            - sglang.launch_server
            - --model-path
            - /models/Meta-Llama-3.1-8B-Instruct
            - --port
            - "8000"
            - --host
            - "0.0.0.0"
          resources:
            limits:
              nvidia.com/gpu: "1"
              memory: "32Gi"
              cpu: "8"
          ports:
            - containerPort: 8000
          readinessProbe:
            httpGet:
              path: /health
              port: 8000
            initialDelaySeconds: 45
            periodSeconds: 10
Architectural Recommendation
- Choose SGLang if your primary workload involves Agents, Tool Use, or RAG, where large chunks of system prompts are shared across successive calls.
- Choose vLLM if you need maximum model support, multi-modal vision-language models, or integrations with the broadest set of orchestrators and backends.
- Choose TensorRT-LLM if you have fixed model topologies deployed in hyper-scale homogenous clusters (e.g. 50+ H100s) and a dedicated team to manage TRT engine builds.
// ABOUT THE AUTHOR
Joshua Edward McLaughlin Cox
Technomancer & Systems ArchitectPassionate about low-level Linux systems engineering, high-scale Kubernetes deployments, local artificial intelligence pipelines, and defensive security. Building robust, sovereign computing environments that stand the test of time.