





Demystifying eBPF: Tracing Linux Kernel Internals in Real Time
For decades, extending the Linux kernel meant writing and inserting out-of-tree Kernel Modules (LKM). While powerful, one null-pointer dereference or unchecked buffer in an LKM would crash the entire machine with a kernel panic.
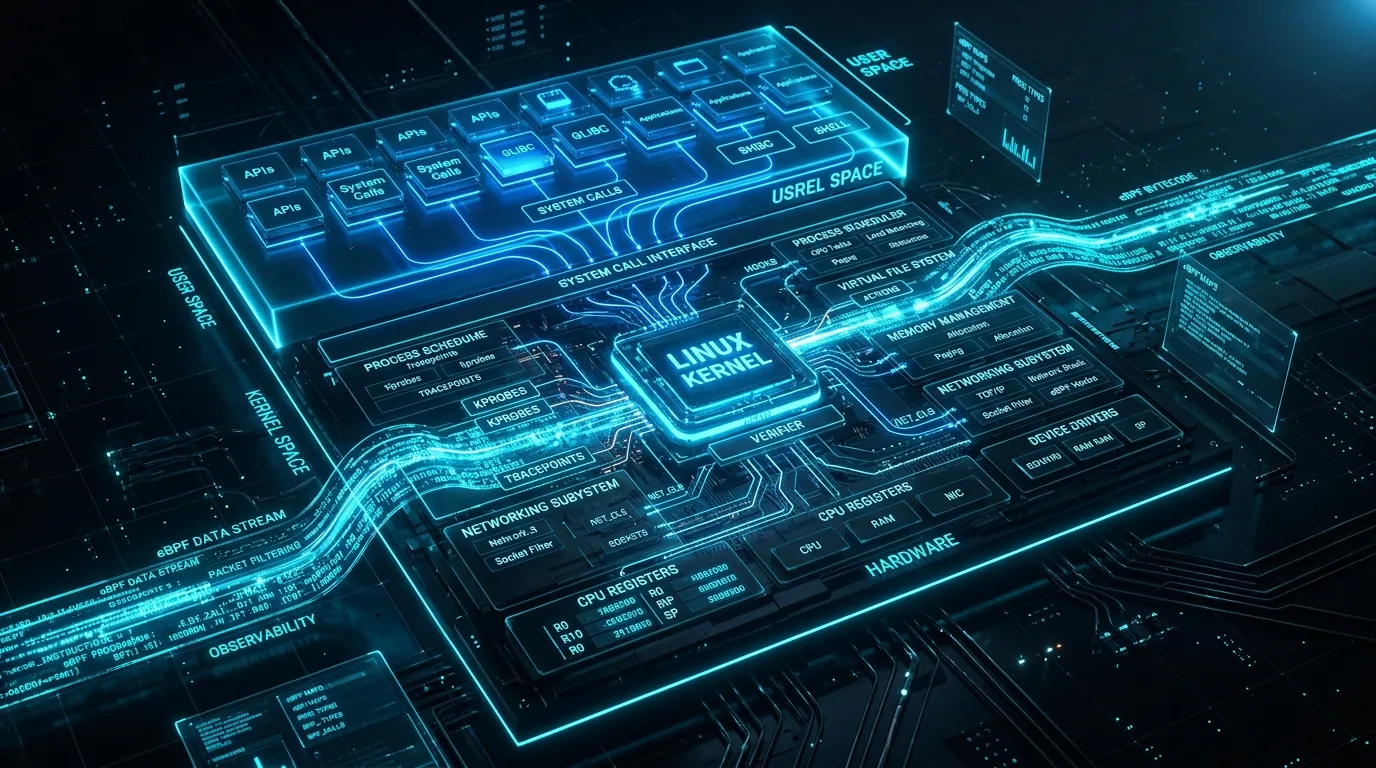
Enter eBPF (extended Berkeley Packet Filter)—the single most transformative technology introduced to Linux systems engineering in the last decade. eBPF allows developers to run sandboxed byte code directly inside the Linux kernel at runtime, without modifying kernel source code or loading untrusted modules.
How the eBPF Verifier Works
Before any eBPF program is attached to a kernel hook (kprobes, tracepoints, or XDP network hooks), it must pass the Linux kernel verifier. The verifier performs rigorous static analysis to guarantee:
- Termination: The program cannot loop infinitely or hang the CPU.
- Memory Safety: Out-of-bounds pointer arithmetic is forbidden; pointers must be dereferenced using helper functions or direct validated memory regions.
- Privilege Checks: Only users with
CAP_BPForCAP_SYS_ADMINcan load programs that probe sensitive kernel data.
+-------------------------------------------------------------+
|                      User Space                             |
|  bpftrace / bcc / Go (cilium/ebpf) / Rust (Aya)             |
+------------------------------+------------------------------+
                               | bpf() syscall (BPF_PROG_LOAD)
                               v
+-------------------------------------------------------------+
|                      Linux Kernel                           |
|  [ In-Kernel Verifier ] ---> [ JIT Compiler (x86_64/ARM64) ]|
|                                     |                       |
|  Hooks:                             v                       |
|  kprobe / tracepoint / sockops / XDP / cgroups               |
+-------------------------------------------------------------+
Quick Tracing with bpftrace
To demonstrate the sheer power of eBPF, we can inspect every execve system call happening across the entire operating system in real time using a one-liner:
# Trace all new processes spawning across all namespaces
sudo bpftrace -e 'tracepoint:syscalls:sys_enter_execve {
    printf("PID: %-6d CMD: %s -> %s\n", pid, comm, str(args->filename));
}'
Sample output:
Attaching 1 probe...
PID: 418290 bash   -> /usr/bin/git
PID: 418292 git    -> /usr/bin/ssh
PID: 418293 ssh    -> /usr/bin/ssh-askpass
Inspecting Block I/O Latency
Disk latency issues can cripple high-throughput databases like Postgres or distributed filesystems. With eBPF, we can measure block device latency without sampling overhead:
# Measure block I/O request-to-completion latency distribution
sudo bpftrace -e '
kprobe:blk_account_io_start { @start[arg0] = nsecs; }
kprobe:blk_account_io_done /@start[arg0]/ {
    @latency_us = hist((nsecs - @start[arg0]) / 1000);
    delete(@start[arg0]);
}'
The output gives you a microsecond-accurate power-of-two histogram:
@latency_us:
[16, 32)             42 |@@                                      |
[32, 64)            312 |@@@@@@@@@@@@                            |
[64, 128)          1048 |@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@@|
[128, 256)          420 |@@@@@@@@@@@@@@@@                        |
[256, 512)           18 |@                                       |
Writing Modern eBPF with CO-RE
Historically, BPF programs required kernel headers installed on the target machine (linux-headers-$(uname -r)). Today, modern eBPF uses CO-RE (Compile Once – Run Everywhere) via BTF (BPF Type Format).
Here is a minimal C snippet targeting sys_enter_openat:
#include "vmlinux.h"
#include <bpf/bpf_helpers.h>
#include <bpf/bpf_tracing.h>

SEC("tracepoint/syscalls/sys_enter_openat")
int trace_openat(struct trace_event_raw_sys_enter *ctx) {
    u32 pid = bpf_get_current_pid_tgid() >> 32;
    char comm[16];
    bpf_get_current_comm(&comm, sizeof(comm));

    bpf_printk("openat called by %s (PID: %d)\n", comm, pid);
    return 0;
}

char LICENSE[] SEC("license") = "GPL";
The Tekromancy Verdict
eBPF is not just a profiling tool—it is the foundational engine of next-generation cloud infrastructure. Projects like Cilium use it to bypass the Linux TCP/IP stack for microservice communication, while security engines like Tetragon detect malicious privilege escalations in kernel space before syscall execution completes.
Stay tuned for our follow-up post where we implement a custom XDP packet firewall running at 40 Gbps line rate!
// ABOUT THE AUTHOR
Joshua Edward McLaughlin Cox
Technomancer & Systems ArchitectPassionate about low-level Linux systems engineering, high-scale Kubernetes deployments, local artificial intelligence pipelines, and defensive security. Building robust, sovereign computing environments that stand the test of time.